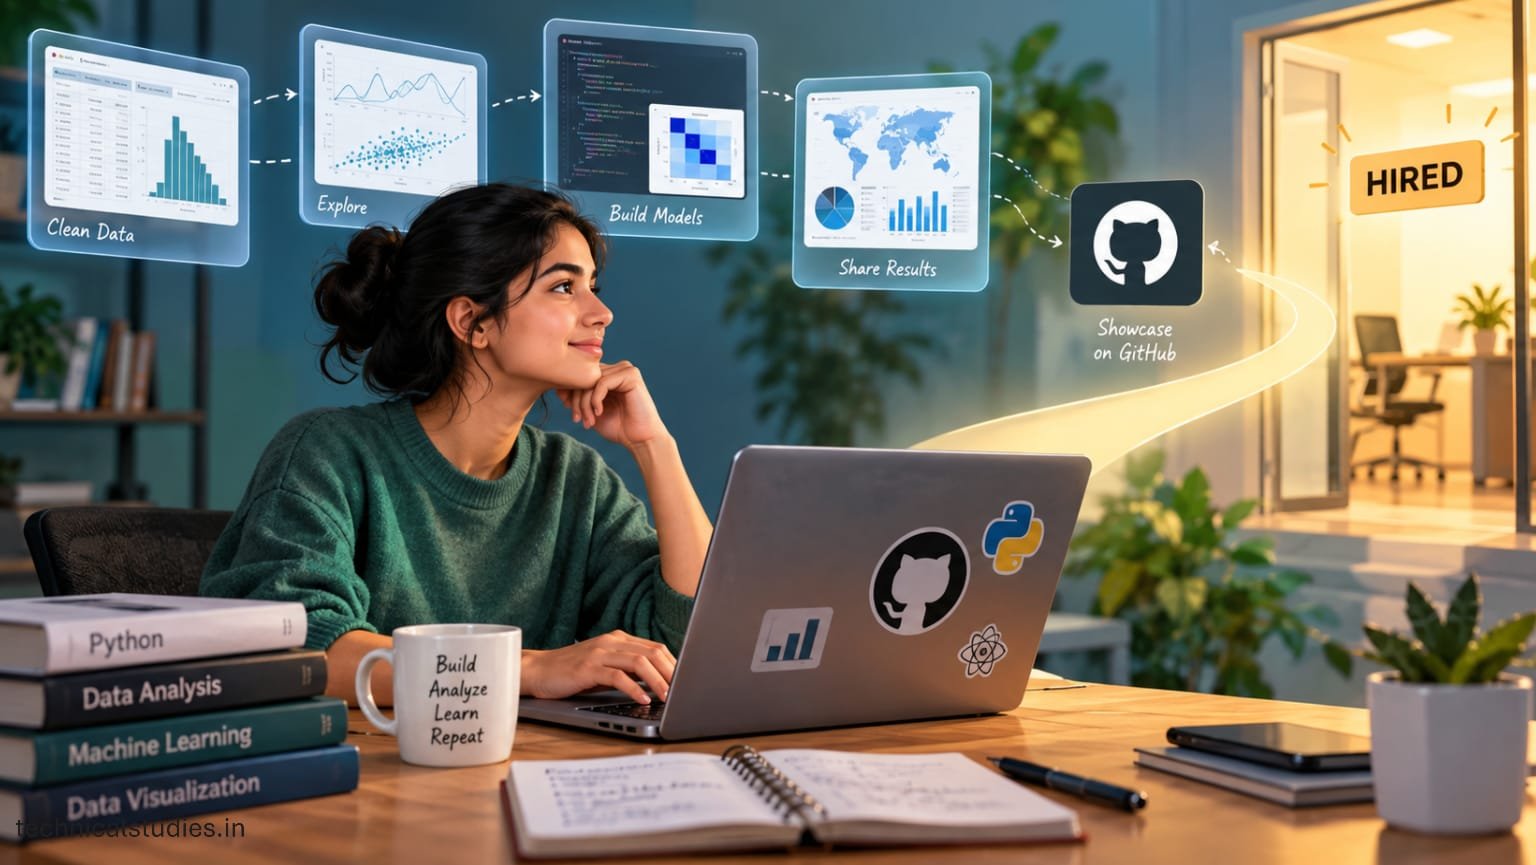
Learn how to build a data science portfolio that gets you hired: pick the right projects, set up GitHub, write strong READMEs, and present your work.
You finished the courses. You have the certificates. So why aren’t recruiters replying?
A certificate tells them you finished a curriculum. It doesn’t show whether you can take a messy dataset, decide which question is worth asking, and explain the answer to someone who doesn’t care about p-values.
Courses hand you clean data and a clear goal. Real work rarely does.
That’s the gap a portfolio fills. It shows how you think: how you frame a problem, handle ugly data, pick a method, and decide what to do when the results are unclear. One well-documented project tells a hiring manager more than a page of badges.
One honest caveat, though. A portfolio won’t get you hired on its own.
It opens doors, but you still need solid technical skills, clear communication, and a decent showing in interviews.
In this guide, we’ll cover how to pick projects worth building, set up your GitHub so it’s easy to browse, write documentation people actually read, and present your work so it sticks.
What Is a Data Science Portfolio, and Why Does It Matter?
A data science portfolio is a small collection of projects that shows your work instead of describing it. Each project usually includes the code, a write-up of the problem and your approach, the results, and a clear explanation of what those results mean.
Some people add a short blog post or a live dashboard, but the core is simple: evidence that you can do the job.
Projects show things a resume can’t. How you cleaned the data reveals your patience and judgment.
Your choice of model shows what you understand. The way you explain a finding shows whether you can think like an analyst, not just run code.
A portfolio also works alongside everything else you have. Your resume makes a claim, such as “built a churn prediction model.” The portfolio proves it.
Certificates show you learned the tools, and projects show you used them. In interviews, your projects become ready-made stories, so you’re never scrambling for examples.
Students, freshers, and career switchers benefit most, since they lack job history to point to. But anyone aiming for a data role can use one.
Also Read: How to Learn Data Science Without A Degree – A Complete Roadmap
What Should a Data Science Portfolio Include?
Every project should walk a reader from question to conclusion. These are the pieces that make that path easy to follow.
A Clear Project Objective
Open with the problem in plain language. “Predict which customers will cancel next month so the retention team can call them first” beats “Build a classification model on telecom data.” Say who would use the answer and what they’d do with it.
Data Collection and Preparation
Name your data source and explain why you chose it. Then show your decisions: why you dropped some missing values, filled others, and removed certain outliers. Decisions matter more than the cleaning code itself, because they reveal your judgment.
Exploratory Data Analysis
Skip the dump of twenty default charts. Pick the few visuals that taught you something, and write one sentence under each saying what you noticed and what you did about it.
Statistical Analysis or Machine Learning
Explain why you picked your method. If logistic regression was enough, say so. Choosing a simple model for good reasons impresses more than a complex one nobody can justify.
Results and Evaluation
Compare your model against a baseline, even a naive one, so the numbers mean something.
Choose metrics that fit the problem (accuracy misleads on imbalanced data). Then be upfront about limitations: small sample, missing variables, possible bias.
Business or Practical Recommendations
Translate findings into action. “Customers on month-to-month plans churn at twice the rate, so target them with annual-plan offers” is something a manager can act on.
Reproducible Code and Documentation
Include a clean README, a requirements file, dataset links, and run instructions. If a stranger can’t reproduce your results in ten minutes, they probably won’t try.
How Many Projects Should a Data Science Portfolio Have?
Fewer than you think. A recruiter might spend a couple of minutes on your portfolio, so ten half-finished notebooks lose to three projects that are clear, complete, and well explained. Quality is what gets remembered.
Three is a solid starting point, as long as they don’t repeat each other. A good mix looks like this:
- A data analysis project. Take a messy dataset, ask sharp questions, and present insights through clean visuals and written conclusions. This shows analytical thinking and communication.
- A machine learning project. Frame a prediction problem, compare models against a baseline, and evaluate honestly. This shows technical depth.
- An end-to-end project. Collect or pull data, clean it, build a model, and deploy it as a simple app or dashboard. This shows you can finish something that works outside a notebook.
Add a fourth or fifth project only when it brings something new, such as a different domain, a new skill like NLP or time series, or a stronger problem than your current weakest one. If it’s another Titanic-style classifier with a different dataset, skip it.
Sometimes the best move is replacing an old project rather than adding a new one.
Also Read: 11 Data Science Mistakes Beginners Make (And How to Avoid Them)
How to Choose the Right Data Science Portfolio Projects
The best project isn’t the most impressive one. It’s the one that fits the job you want and that you can talk about for ten minutes without stalling.
Start With Your Target Job Role
Open five job postings for the role you’re aiming at and highlight the repeated skills. A data analyst posting might stress SQL, dashboards, and stakeholder communication.
A machine learning role might want model deployment and experiment tracking. Build projects that prove those specific skills, not a generic mix.
Solve a Specific Problem
“Analyze airline data” is a topic. “Which routes lose the most passengers to delays, and is it worth adding buffer time?” is a project. A narrow question gives you a clear finish line and a story with a beginning and an end.
Use Credible and Accessible Datasets
Good starting points include Kaggle, the UCI Machine Learning Repository, government open-data portals, and public APIs.
Prefer data with a clear origin and documentation. Whatever you pick, record where it came from, when you downloaded it, and its license in your README, so no one wonders if it’s legitimate.
Go Beyond Following a Tutorial
Tutorials are fine for learning, but a copied tutorial project looks identical to hundreds of others.
Change the dataset, ask your own question, and justify your modeling choices. If results turn out underwhelming, say so and explain why. Honest interpretation reads as maturity.
Choose Projects You Can Explain
If an interviewer asks why you filled missing values with the median, or what your model gets wrong, you need a real answer.
Before publishing, check that you understand every line of code, your method, your results, and your limitations. If you can’t explain it, simplify it until you can.
Best Data Science Portfolio Project Ideas for Beginners
These five ideas are common, which is fine. What makes them stand out is how you execute them.
1. Exploratory Data Analysis of Retail Sales
Skills: Python, pandas, visualization, SQL where relevant.
Goal: Find sales patterns, top and bottom products, and customer trends. Which categories drive revenue, and which quietly lose money?
Deliverable: An analysis notebook and a one-page findings report.
2. Customer Churn Prediction
Skills: Data preprocessing, classification, feature engineering, model evaluation.
Goal: Flag customers likely to leave a service.
Deliverable: An evaluation report with suitable metrics (recall often matters more than accuracy here) and a section on limitations.
3. Customer Segmentation
Skills: Exploratory analysis, clustering, feature scaling, visualization.
Goal: Group customers by purchasing or behavioral traits.
Deliverable: Segments someone can actually describe (“occasional big spenders” beats “Cluster 2”) plus ideas for how a business could use them.
4. Sales Forecasting
Skills: Time-series analysis, baseline forecasting, error metrics.
Goal: Estimate future sales from historical data.
Deliverable: Forecast charts and a discussion of where and why predictions miss. Start with a naive baseline, like repeating last month’s numbers, so you can show your model earns its complexity.
5. Sentiment Analysis of Text Reviews
Skills: Text preprocessing, NLP, classification.
Goal: Classify the sentiment of product or service reviews.
Deliverable: Model results, example predictions, and an error analysis. Show the reviews your model got wrong, such as sarcasm, and explain why.
Any of the projects above can look like a tutorial exercise or a real piece of work. The difference comes down to a few habits –
- Write a clear problem statement. Say who needs the answer and why.
- Set a baseline or compare approaches. Numbers only mean something next to a point of comparison.
- Explain your evaluation choices. Why that metric, and why not another?
- Add useful visuals and practical recommendations. Tell the reader what to do with the findings.
- Document limitations and next steps. Naming your project’s weaknesses shows you understand it.
How to Build a Data Science Portfolio on GitHub
GitHub is where most recruiters will look, so treat it like a storefront, not a storage unit.
Create a Professional GitHub Profile
Use your real name and a clear photo. Write a one-line bio that states your focus, such as “Data analyst interested in retail and healthcare analytics.”
Add your LinkedIn and portfolio links, and set up a short profile README that says who you are and what you’re working on.
Organize Each Project Repository
A tidy structure helps a visitor find things fast –
- README.md
- notebooks/
- src/
- data/ (or download instructions)
- reports/ or images/
- requirements.txt or an environment file
Scale this to the project. A single-notebook analysis doesn’t need a src/ folder. Never commit large, private, or restricted datasets. Link to the source and explain how to download it instead.
Write Clean and Readable Code
Use names that say what things are (monthly_revenue, not df2). Move repeated logic into functions.
Comment on why you did something, not what each line does. Before pushing a notebook, clear stray outputs and error messages, and run it top to bottom to confirm it works.
Make Projects Easy to Reproduce
Your README should cover installing dependencies, getting the data, and running the code, in that order. Then test it yourself by cloning the repo into a fresh folder and following your own steps. You’ll catch missing files fast.
Pin Your Best Projects
GitHub lets you pin six repositories to your profile. Choose three or four that match your target role, and put the strongest first. Give each a clear repo name and a short description so a recruiter understands it in seconds.
Also Read: Best Machine Learning Courses for Beginners: Start Learning ML the Right Way
How to Write a Data Science Project README
Your README is the front door to your project. Most visitors will read it and nothing else, so make it count.
Project Title and One-Sentence Summary
Name the project for what it does, then add one sentence on why it matters. “Telecom Churn Predictor: identifies customers likely to cancel so retention teams can act early.”
Problem Statement and Objectives
State the question, the scope, and the outcome you were after. Mention what you deliberately left out.
Dataset and Data Preparation
Give the source link, key variables, license, and download date. Summarize your main cleaning decisions in a few lines.
Tools and Methodology
List your libraries and explain your approach and why you chose it.
Results and Key Findings
Report your metrics next to the baseline, plus two or three real insights. Avoid claims your data can’t support.
Visualizations and Project Demo
Embed one or two charts that carry the story. If you built an app, add a screenshot or live link.
Limitations and Future Improvements
Say what the project doesn’t prove, such as a small sample or missing variables, and what you’d try next.
How to Run the Project
Give exact steps: clone, install, get the data, run.
A README Template You Can Copy
# Project Title
One-sentence summary of what it does and why it matters.
## Problem Statement
The question, scope, and intended outcome.
## Dataset
- Source: [link]
- License:
- Key variables:
- Preprocessing:
## Methodology
Tools, methods, and why you chose them.
## Results
| Model | Metric |
|-------|--------|
| Baseline | |
| Final model | |
Key findings:
## Visuals / Demo

## Limitations & Next Steps
-
## How to Run
1. git clone [repo]
2. pip install -r requirements.txt
3. Download data from [link] into data/
4. jupyter notebook notebooks/analysis.ipynb
How to Tailor Your Portfolio to Different Data Careers
“Data roles” is a loose label. An analyst, a scientist, and an ML engineer get hired for different strengths, so one generic portfolio rarely serves all three.
Data Analyst Portfolio
Analysts are hired to turn messy data into decisions. Show SQL queries that join and aggregate real tables, a cleaning process you can defend, and a dashboard in Tableau, Power BI, or Looker Studio.
Most important, include a short written summary a non-technical manager could read and act on. Communication carries more weight here than model complexity.
Data Scientist Portfolio
Scientists are expected to reason with evidence. Feature a project with solid statistical thinking: a hypothesis test or A/B test analysis, thoughtful feature engineering, model comparison against a baseline, and an honest interpretation of what the results do and don’t mean. Explaining why a model works matters as much as the score.
Machine Learning Engineer Portfolio
Here, the model is only half the job. Show that you can package it: a reproducible training pipeline, unit tests, a REST API (FastAPI or Flask), a Docker container, and a deployed demo.
Clean repo structure and version control count heavily, because this role sits close to software engineering.
Match Projects to Job Descriptions
Collect five to ten postings for your target role and paste them into a spreadsheet. Tally the tools and skills that appear repeatedly. If SQL shows up in nine of ten, a SQL-heavy project is non-negotiable. If three mention experiment design, add one.
Then audit your portfolio against that list. Wherever a frequent skill has no matching project, that’s your next build. Where a project covers nothing on the list, consider retiring it.
Also Read: Top 10 Udemy Courses for Aspiring Data Scientists
How to Build a Data Science Portfolio With No Experience
No job history doesn’t mean no evidence. You just have to create it yourself.
Start with public datasets and define your own problem. Nobody assigned it, and that’s the point: choosing a worthwhile question shows initiative.
Your coursework is also raw material. Take a class assignment and push it further. Add a new question, bring in a second dataset, or test a different method and explain what changed. A deepened assignment looks nothing like a submitted one.
Get the fundamentals right before reaching for anything fancy. A well-cleaned dataset, a sensible baseline, and a clear explanation beat a neural network you can’t justify.
If you’re comfortable with it, contribute to open source. Fixing documentation, adding an example, or resolving a small issue in a data library counts, and it shows you can work in someone else’s codebase.
For group projects, state exactly what you built (“I wrote the preprocessing pipeline and evaluated three models”) rather than claiming the whole thing.
Make the work easy to find by linking your best projects from your resume, LinkedIn, and GitHub profile.
Finally, be upfront about shortcuts. If you used simulated data, say so. List your assumptions and limitations in the README. Honesty here builds more trust than a polished result with hidden gaps.
How to Present Your Data Science Portfolio When Applying for Jobs
Having a good portfolio is half the job. The other half is making sure the right person sees the right project.
Tailor what you show. If you’re applying to a retail analytics team, lead with your sales analysis, not your sentiment classifier.
Mention the most relevant project in your cover note or application message, and link directly to that repository instead of a general profile page.
Your resume bullets should read like mini case studies: the problem, what you did, the method, and a result you can verify.
For example: “Built a churn model on 7,000 telecom records using gradient boosting; improved recall from 48% to 71% over a logistic regression baseline.” Only include numbers you can back up.
Then prepare to defend the work. Expect questions about why you chose a method, how you handled missing data, and where the model fails.
Also rehearse one answer that surprises people: what you’d do differently if you started over. A thoughtful answer about a better validation strategy or a missing feature shows growth.
Finally, treat your portfolio as a living thing. Update it as your skills improve, and retire projects that no longer reflect your best work.
Frequently Asked Questions
How many projects should a data science portfolio have?
Start with three strong, different projects: one analysis, one machine learning, and one end-to-end. Add more only when a new project shows a skill your current ones don’t.
Can I build a data science portfolio without work experience?
Yes. Use public datasets, define your own questions, and deepen coursework projects. Be clear about your methods, assumptions, and limitations so reviewers trust your work.
Is GitHub enough for a data science portfolio?
For most roles, yes, if your READMEs are clear. Add a short blog post or live dashboard if you want non-technical recruiters to grasp your work quickly.
Which data science projects are best for beginners?
Retail sales analysis, churn prediction, customer segmentation, sales forecasting, and sentiment analysis. Each covers core skills, so choose based on the role you want.
Do I need to deploy my data science projects?
Not for every project. Analyst roles rarely require it, but for machine learning engineer roles, one deployed project with an API or simple app is valuable.
How do I include portfolio projects on my resume?
Write each as a short case study: the problem, your method, and a verifiable result. Add a direct link to the repository next to the project title.
Can a data science portfolio help me get my first job?
It can. A strong portfolio gets you interviews by proving practical skill, but you still need solid fundamentals, clear communication, and good interview performance to land the offer.
Conclusion: Start Building a Portfolio That Demonstrates Your Skills
A great portfolio isn’t about volume or flashy models. It’s a few projects that are relevant to your target role, finished properly, and clear enough that you can explain every decision in them.
Don’t wait until you have five. Publish one strong project first, even if it feels a little rough. A live, documented repository beats a perfect idea sitting in your head.
So do this today, before you close this tab: pick the role you want, find one public dataset that fits it, and write a one-sentence problem statement. Then open a new GitHub repository and commit your README.
That’s your first project, officially started.
Related Articles
Best PyTorch Courses for Beginners: Learn Deep Learning Step by Step
Best Free Python Courses on Udemy: Learn Python Without Paying
Best ChatGPT Courses for Beginners With No AI Experience
Best Deep Learning Courses with Hands-On Projects: Learn AI Through Real-World Projects
TechnicalStudies was started by Neeladrinath with one simple idea — give Indian students a reliable place to figure out what’s actually worth their time and money. Every recommendation here is backed by careful research, real student feedback, and honest analysis. We cover online courses, laptops, smartwatches, software deals, and learning resources — all looked at from a student’s perspective, so you can spend less time guessing and more time learning.